

PostgreSQL: max_parallel_workers Doesn't Do What Its Name Suggests
Christophe Pettus breaks down two parallelism GUCs that every DBA misconfigures at least once: one governs per execution-plan node, the other competes for a shared pool without telling anyone.

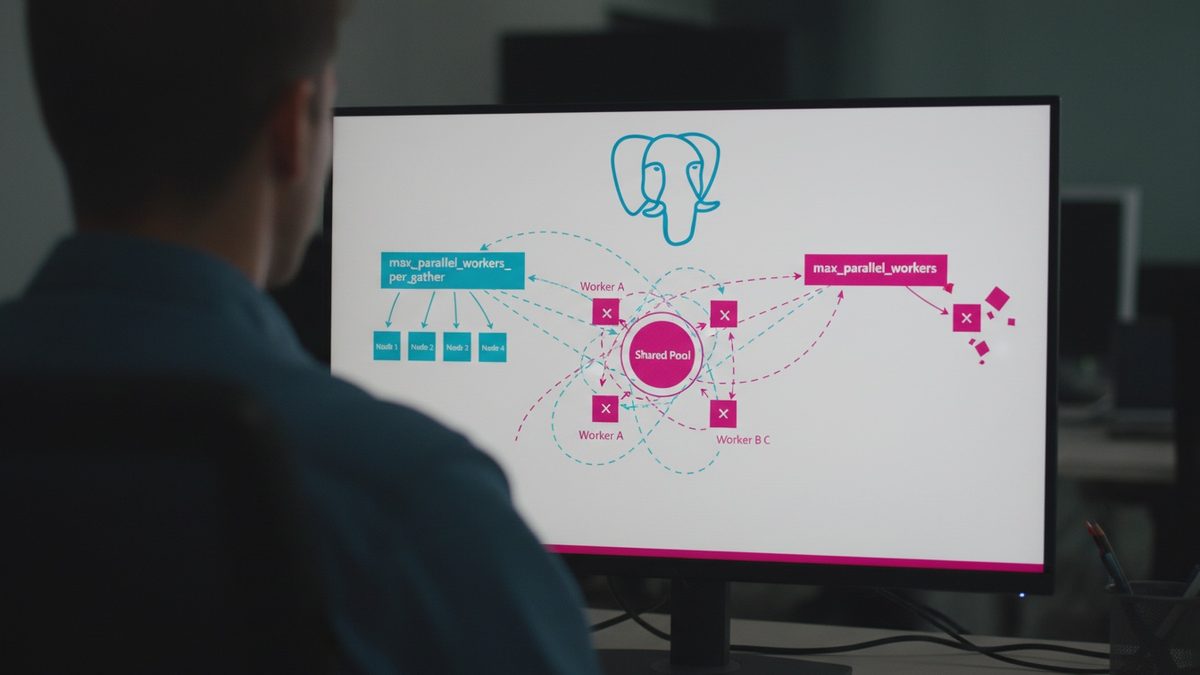
Christophe Pettus, on the Planet PostgreSQL blog, published another chapter in the "All Your GUCs in a Row" series and picked a pair of parameters that tends to confuse even people who have worked with parallelism for years: max_parallel_workers_per_gather and max_parallel_workers. The article's central argument is direct: neither of them does exactly what its name promises, and the difference between them explains a good part of the execution plans that "should" be parallel and aren't.
What Each GUC Actually Controls
max_parallel_workers_per_gather is the ceiling on workers that the planner can request for a single Gather or Gather Merge node in the plan. It arrived in PostgreSQL 9.6 along with parallel query, with a default value of 0 (that is, disabled). Version 10 turned on parallelism by default by raising this value to 2, and created max_parallel_workers in the same release to prevent parallel queries from taking over the server's entire pool of background workers.
max_parallel_workers, in turn, is documented as a limit for the entire cluster, but in practice it's enforced in a much more fragile way: by comparing a global count (in shared memory) against a value that each session chooses for itself. This asymmetry is the root of almost every strange behavior Pettus describes in the article.
Both accept values from 0 to 1024 and are of user context, which means any role can change them with a simple SET, without any special privilege.
How the Planner Decides How Many Workers to Request
The planner never reads max_parallel_workers_per_gather directly to decide the estimate; it calculates a number of workers based on the expected size of the table read, using min_parallel_table_scan_size (8MB by default) as a base: one worker starting at 8MB, and one more each time that value triples. This yields a known progression: 24MB requests two workers, 72MB requests three, 216MB four, 648MB five, 1.9GB six, 5.7GB seven, and the eighth only shows up starting at 17GB. A 10GB table, therefore, will never request more than seven workers, no matter how much the per-gather limit is raised. That's why raising max_parallel_workers_per_gather to 16 on a database whose largest tables add up to a few gigabytes changes much less than intuition suggests: the parameter is a ceiling, not an incentive.
There are two ways to get around this size rule. The first is the parallel_workers storage parameter (ALTER TABLE t SET (parallel_workers = 16)), which replaces the automatic calculation for that specific table. The second is enable_parallel_append: when enabled, a Parallel Append node requests at least log2 of the number of partitions plus one, so 64 small partitions already request seven workers regardless of each one's individual size. In both cases, the max_parallel_workers_per_gather ceiling still applies.
One detail that goes unnoticed: the name says "per gather" and it's literal. A plan with two Gather nodes can consume double the configured limit (Pettus reports having observed a merge join between two Gather Merge subplans running four simultaneous workers with the parameter set at 2). Furthermore, since parallel_leader_participation is enabled by default, the leader process also executes part of the parallel work, so "2" in practice means three processes, each with its own slice of work_mem.
The Cluster-Wide Limit That Isn't Really a Limit
The most counterintuitive part of the article is how max_parallel_workers is actually enforced. In the PostgreSQL 18 source code, it's consulted in exactly one line: inside RegisterDynamicBackgroundWorker(), which refuses a new parallel worker when the number already running has hit the limit. The planner never looks at this value when building the plan. Practical consequence: setting max_parallel_workers = 0 doesn't disable parallel query. The plan keeps being generated as if it had help, except nobody shows up to execute it:
SET max_parallel_workers = 0;
EXPLAIN (ANALYZE, COSTS OFF, TIMING OFF, BUFFERS OFF)
SELECT count(*) FROM t WHERE k = 7;
 Finalize Aggregate (actual rows=1.00 loops=1)
 -> Gather (actual rows=1.00 loops=1)
 Workers Planned: 2
 Workers Launched: 0
The leader executes everything alone, using a plan costed based on the expectation of help that never arrives. To truly disable parallelism, the correct GUC is max_parallel_workers_per_gather = 0. And the worst part: a refused worker generates no error and logs nothing. The only evidence is the difference between Workers Planned and Workers Launched in EXPLAIN (ANALYZE), which in practice means discovering the problem one query at a time, after someone complains about slowness.
The "Hostile Intern" Scenario
Since the count that matters is global but the limit compared is per session, Pettus builds a revealing scenario: with max_parallel_workers = 2 in postgresql.conf, a role with no privilege beyond SELECT on a table can do this:
SET max_parallel_workers = 1024;
SET max_parallel_workers_per_gather = 64;
SET min_parallel_table_scan_size = 0;
The result, with max_worker_processes at its default of 8 (one slot already taken by the logical replication launcher), was a plan requesting ten workers and getting seven; meanwhile, while this query ran, another session with a parallel plan launched no worker at all, and a CREATE SUBSCRIPTION created on the same server was left without an apply worker, with no visible error beyond a WARNING: out of background worker slots repeated in the log every five seconds. The replica only started working again once the query was canceled. It doesn't take a malicious intern: it's enough for someone to paste a SET max_parallel_workers = 64 copied from a blog into an overnight reporting job.
PostgreSQL 18 Gives Visibility to the Problem
Up through version 17, the only way to monitor this was to count rows with backend_type = 'parallel worker' in pg_stat_activity (grouping by leader_pid to know whose they are) and compare against the configured limit. PostgreSQL 18 solves this natively: pg_stat_database and pg_stat_statements gained the parallel_workers_to_launch and parallel_workers_launched columns. A growing difference between the two is a direct sign that the pool is undersized, and this becomes something that can be monitored in aggregate, not query by query.
How to Tune in the Right Order
Pettus's recommendation is to configure these parameters in reverse alphabetical order. First max_worker_processes, because it requires a restart and is the only truly rigid limit of the three, shared with logical replication (max_logical_replication_workers) and whatever extensions register. The suggested math: max_parallel_workers plus max_logical_replication_workers plus whatever extensions use, plus a buffer of four to eight. For max_parallel_workers, the suggested number is two to three times the number of cores, dropping to about 1.5x on machines with 32 or more cores, generous on purpose because the cost of an exhausted pool is a parallel plan executed by a single process.
max_parallel_workers_per_gather should stay at 2 globally on any instance serving OLTP traffic, raised only where there are genuinely large scans, via ALTER ROLE ... SET max_parallel_workers_per_gather = 6. Going above 8 rarely pays off, unless the volume scanned is in the tens of gigabytes; in that case, the correct route is the parallel_workers storage parameter on the specific table. Finally, it's worth hunting through pg_db_role_setting, the application code, and cron jobs for any forgotten SET max_parallel_workers: it's that value, not the one in postgresql.conf, that effectively becomes the cluster's ceiling.
For those building on PostgreSQL and relying on heavy analytical queries coexisting with OLTP on the same cluster, the practical takeaway is clear: before blindly raising max_parallel_workers_per_gather on a slow query, it's worth running EXPLAIN (ANALYZE) and comparing Workers Planned with Workers Launched. If the difference is zero, the problem isn't in the gather, it's in the shared pool, and the fix goes through max_worker_processes, not the parameter that seems most obvious.
Translated from the Brazilian Portuguese original · Read the original
Web tool inspects PostgreSQL pg_dump without restoring to a server
PostgreSQL Dump Viewer replays the backup file inside the browser to check tables, foreign keys, and run read-only SQL before any real restore.




