

Mistral Large 4 arrives in preview with 1 trillion parameters, but open weights only by the end of October
The benchmark leap is real, but the open weights, which underpin the promise of running on-premise, are only expected by the end of the month.

Mistral launched a preview of Large 4 via API this Tuesday (October 6), a model with 1 trillion parameters but only 49 billion active per token. The benchmark leap is real, but the open weights, which underpin the promise of running on-premise, are only expected by the end of the month.
The announcement, made this Tuesday (October 6)
Mistral AI published a preview of Mistral Large 4 this Tuesday, October 6, 2026, accessible through the company's own API. The most detailed account of the launch came from Simon Willison's blog, who closely follows every new relevant language model on the market.
The numbers draw attention: 1 trillion parameters in total, but only 49 billion active per token. The model was trained on Mistral's own cluster, with 3,800 NVIDIA Grace Blackwell GPUs.
Under the hood: a very sparse Mixture-of-Experts
The ratio between total and active parameters gives away the architecture: it's a Mixture-of-Experts (MoE), where only a fraction of the model's "experts" participate in each inference. With 49 billion active out of 1 trillion total, the activation rate sits around 5%, a much sparser split than is common for this type of architecture.
In practice, this lowers the computational cost per token processed: the inference bill is closer to that of a ~49B dense parameter model, not a 1T one. The problem is that memory cost doesn't drop along with it: to serve any token, the inference system needs fast access to all possible experts, not just the ones that will be activated.
The benchmark leap, and what it actually means
On Artificial Analysis, the index the LLM community uses as a comparative benchmark, Large 4 scored 38 points. That puts it just behind DeepSeek 4.1 Flash, a 552-billion-parameter model, but well ahead of its direct predecessor.
| Model | Parameters (total / active) | Artificial Analysis score |
|---|---|---|
| Mistral Large 3 (Dec/2025) | not disclosed | 9 |
| Mistral Large 4 (preview, Oct/2026) | 1 trillion / 49 billion | 38 |
| DeepSeek 4.1 Flash | 552 billion (MoE) | slightly above 38 |
Mistral Large 3, released in December 2025, had scored only 9 points on the same index. A jump from 9 to 38 is significant for any vendor, but it still doesn't place Large 4 in the frontier class: Willison estimates the model is about six months behind the state of the art, which is already seen as a competitiveness recovery for Mistral after a weak generation.
The informal test that exposes a quirk in reasoning modes
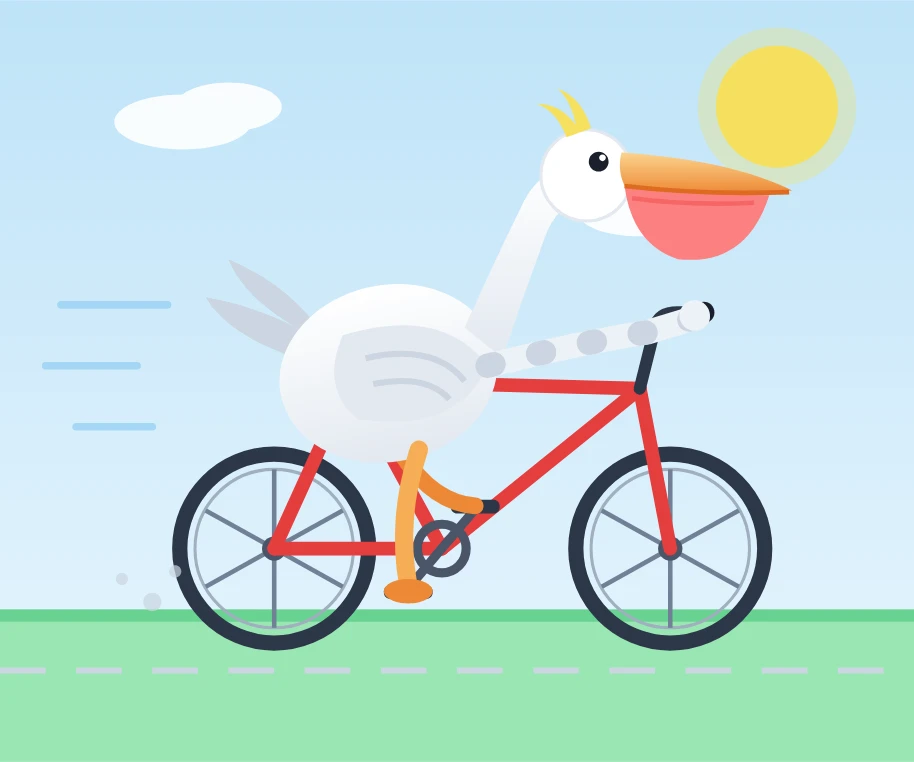
Willison keeps a personal, good-humored benchmark: asking every new model to draw, in SVG, a pelican riding a bicycle. The result doesn't measure general code quality, but it quickly captures whether the model follows complex spatial instructions without supervision.
Large 4 only offers two reasoning levels via the API, none and high, without the intermediate token-budget options other vendors have been offering. The pelican test result was counterintuitive: the high mode produced a better drawing using 2,717 output tokens, while the none mode spent more, 3,275 tokens, and produced a worse result. For anyone deciding between reasoning levels in a production pipeline, this is a reminder that spending more tokens isn't synonymous with applying more reasoning.
The fine print that changes the story's angle
Here's the point that separates today's announcement from the promise of a "European model without vendor lock-in": Large 4's open weights don't exist yet. Mistral has promised to release them only by the "end of this month," that is, by the end of October 2026.
Until that happens, using Large 4 means depending on Mistral's API, exactly the same kind of vendor dependence that any closed model from OpenAI, Anthropic, or Google imposes. There is, today, no way to run this model on-premise. Anyone who decides to integrate the preview into production now is betting on a promise of future openness, not using an already-open model.
What will weigh in once the weights are out
When (and if) the weights are published, the infrastructure bill for running Large 4 locally won't be trivial, even with the MoE's sparsity working in its favor. A model with 1 trillion parameters, even at 8-bit quantization, takes up somewhere around 1 terabyte in weights alone; at 4-bit, it would still be close to 500 gigabytes.
This means that, even though only 49 billion parameters are activated per token, the inference server needs to keep all experts loaded in GPU memory (or in memory fast enough not to generate latency from disk swapping) to serve requests predictably. Serving a MoE of this size requires expert parallelism, which implies a multi-GPU cluster, not a single workstation. Trading the API bill for your own hardware is real, but the hardware involved here isn't small.
Who it's worth waiting for
For teams in Brazil concerned about data sovereignty, or that are already running into API costs at scale, Large 4 is a name to monitor, not to adopt today. The sensible path is to follow the weight release at the end of October, evaluate the real serving requirements (memory, expert parallelism, throughput), and compare the practical result against already-open alternatives, such as DeepSeek's own models, which today already publish weights alongside their benchmarks.
Being six months behind the frontier isn't a problem for most production use cases, which don't require the world's most advanced model, just a competent, predictable one, and, in Large 4's case, potentially free of vendor lock-in once the second half of the promise, the open weights, is finally fulfilled.
Translated from the Brazilian Portuguese original · Read the original
EmbeddingGemma 2 brings multimodal semantic search to phones without heavy GPU
Google DeepMind launched EmbeddingGemma 2, an open model with 740 million parameters that combines text, image, video, and audio in a single vector space and runs with less than 600MB of RAM, without relying on the cloud.

