Does your site exist for AI? Start with the terminal
A site can work normally in the browser and still be inaccessible to AI crawlers. This article presents terminal tests to identify blocks by firewall or CDN and to check whether the content is in the HTML sent by the server. It also explains the order of Technical GEO checks: access, reading, interpretation, and measurement.

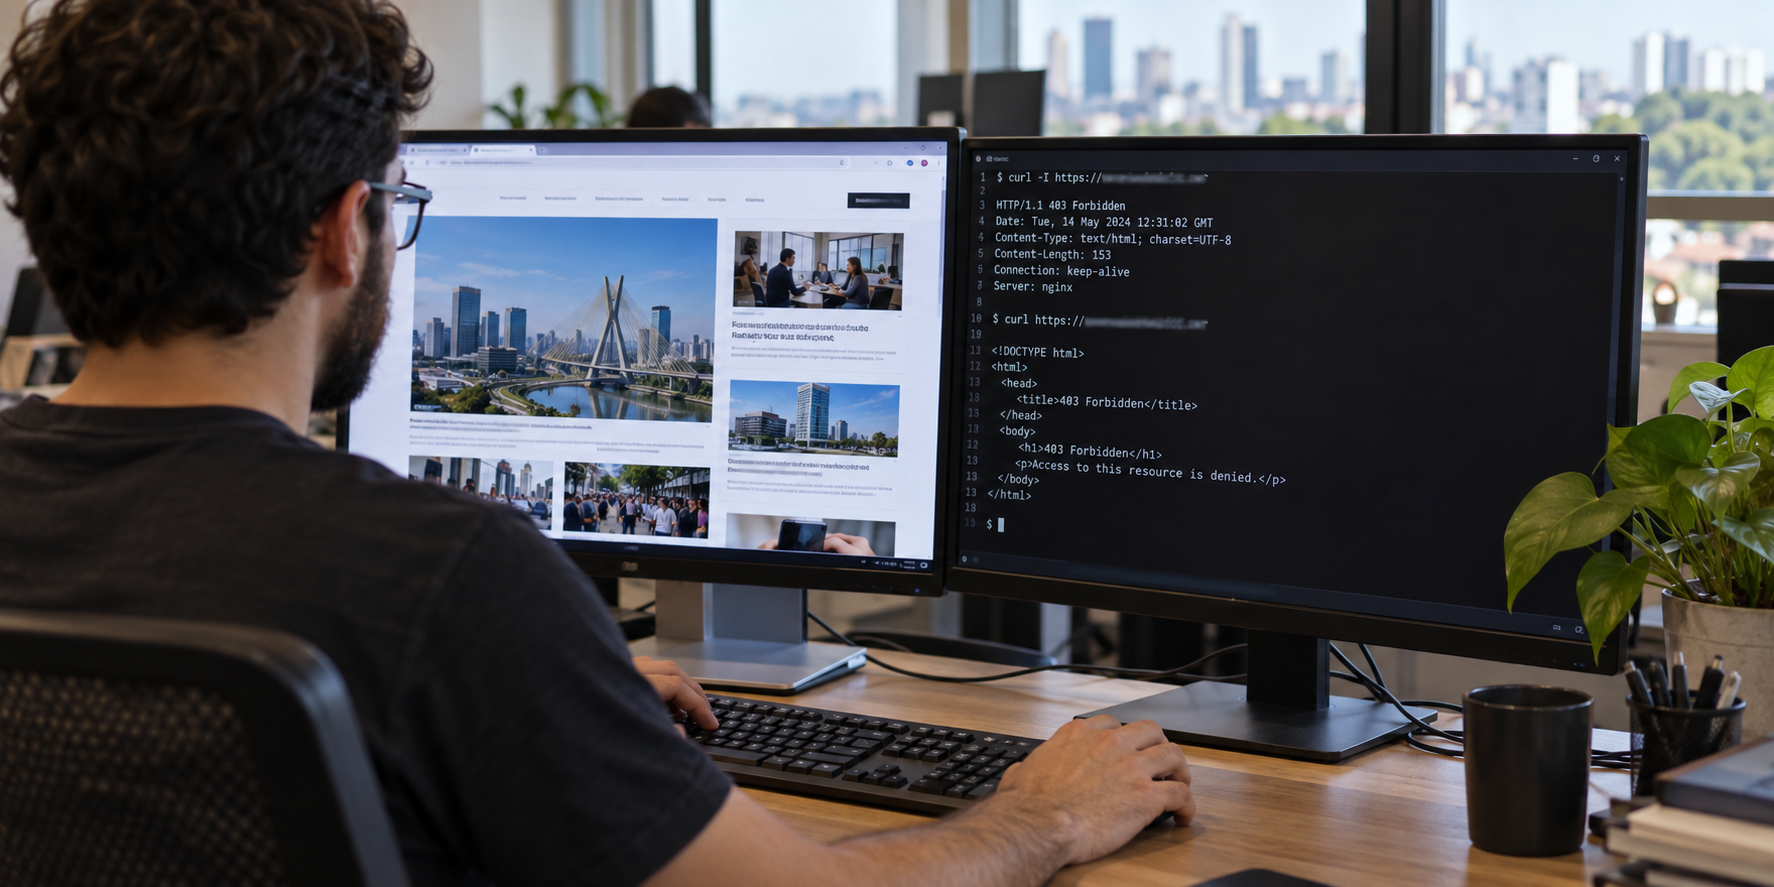
Open a terminal and run these two commands pointing to a site you maintain:
curl -sI -A "Mozilla/5.0" https://seusite.com.br | head -1
curl -sI -A "GPTBot" https://seusite.com.br | head -1
If the first returns 200 and the second returns 403, 429, or 503, your site is blocking AI bots at the front door. And, in most cases I see, nobody decided this. The firewall, the CDN, or the security plugin decided for you.
Now the second test:
curl -s https://seusite.com.br | perl -0777 -pe 's/<(script|style)[^>]*>.*?<\/\1>//gis; s/<[^>]+>//g' | tr -s '[:space:]' ' ' | wc -c
If the result is a number too small for the content you see in the browser, the site's text only exists after JavaScript runs. And most AI crawlers don't execute JavaScript.
These two tests take thirty seconds and sum up a problem that most engineering teams haven't put on the backlog yet: the site can be perfect for humans and, at the same time, not exist for the machines that now answer questions in place of the search engine.
The question changed
For two decades, optimizing a site meant answering one question: how does it show up on Google? That question is being replaced by another: how does the brand show up when an AI answers?
ChatGPT, Gemini, Perplexity, Claude, and the AI modes of search engines don't deliver a list of links. They deliver an answer. To put that answer together, they need to have accessed, read, and interpreted the sources.
If your site fails at any one of these three stages, it isn't a source. It doesn't appear in the answer, isn't cited, doesn't get the click that's left.
And the click that's left is worth more.
In November 2025, data from Microsoft Clarity showed that visitors coming from AI answers convert about three times more than visitors from other channels.
Less volume, much more intent.
GEO is the acronym for Generative Engine Optimization, optimization for generative engines.
Within it, I call Technical GEO the slice that deals with what the developer controls: code, server, configuration. It isn't about narrative, and it isn't about brand. It's engineering.
Three verbs, one order
The definition I use is short: Technical GEO means making sure AI can access, read, and interpret your site.
The three verbs aren't synonyms. They are sequential dependencies:
- AI only reads what it managed to access.
- AI only interprets what it managed to read.
It's a funnel, and the order isn't negotiable.
A flawless JSON-LD schema is worth nothing if robots.txt blocks GPTBot. Excellent content is worth nothing if it only exists in the rendered DOM. Many teams start with the schema because that's what shows up in SEO tools, and find out months later that the crawler never got past the door.
Above the three verbs there is a fourth, which is the result: act.
When the site is accessible, readable, and interpretable, it becomes operable by AI agents, software that doesn't just consume information but fills out forms and navigates flows. Below the three verbs there is a cross-cutting layer: measurement. What isn't measured isn't managed, and without measurement every fix becomes an opinion.
The most common failure is silent
Of the problems I find in audits, the most frequent is also the most invisible: robots.txt allows the crawler, but the WAF or the CDN returns a 403 for its user-agent.
It happens because bot-protection rules classify GPTBot, ClaudeBot, PerplexityBot, and the like as malicious traffic. The site works fine in the browser, Search Console doesn't complain, Lighthouse gives it a green score. And the site has been closed off to AI for months.
The test is the one from the start of the article, repeated for each user-agent you want to allow. The relevant list today includes GPTBot, OAI-SearchBot, ChatGPT-User, ClaudeBot, Claude-User, PerplexityBot, Google-Extended, Applebot-Extended, Meta-ExternalAgent, Amazonbot, and CCBot. It changes often, so treat it as versioned configuration in the repository, not as something you keep in your head.
The second most frequent problem is what I call Response versus Render. The server responds with an HTML; the browser renders a DOM after JavaScript.
Humans see the render. Most AI crawlers see only the response. An SPA without SSR, a theme assembled by a page builder that injects text via JS, a block that fetches content via an API on the client: all of that can be perfect on screen and empty in the raw response.
The test is even simpler than the terminal one: turn off JavaScript in the browser and reload the page. Whatever disappears doesn't exist for the machine.
This isn't just a WordPress problem
I'll dedicate a section of the guide to WordPress, because that's where Apiki has been operating for more than 17 years and where these problems take on specific shapes: security plugins blocking crawlers by default, two SEO plugins generating conflicting schemas, page builders delivering shallow HTML.
But the framework is agnostic. A good share of the projects we maintain today use WordPress only as a CMS, with the front end in React or Next.js. In these cases, the Response versus Render problem is exactly the same as in any JavaScript application, and the solution involves SSR, prerendering, or static generation. One of the next articles in this series will dissect an AI news portal we built with headless WordPress and Next.js, showing what AI gets from each route.
Where to start
If you've made it this far, you have a mental backlog. The order that works is the order of the funnel:
- Access first. If the crawler is blocked, nothing after that matters. It's the fastest check and the one with the biggest impact.
- Then, content in the raw response. Confirm that the text that matters is in the HTML served.
- Then, navigation and entity: sitemap, llms.txt, real internal links in the HTML, a JSON-LD organization block with name, url, logo, and sameAs.
- Finally, accessibility, which is what makes the site operable by agents.
And measure before and after. Every fix needs to become a delta: the score before, the score after, the evidence for each check.
The six layers of the framework, with a checklist and verification commands for each one, are in the guide “Does your site exist for AI?”, which iMasters is distributing. And the whole framework is coded into a free tool: you enter the URL and get a score from 0 to 100, with the result by layer and the fixes in funnel order. It's at geo.apiki.com and takes less than a minute.
A note on methodological honesty: the tool's results page is auditable by itself, and it needs to score well. A diagnosis of GEO that doesn't comply with GEO contradicts its own thesis. Run it on your site. Then run it on ours.
Article by Leandro Vieira
Translated from the Brazilian Portuguese original · Read the original