Fine-tuning became a solution before the problem was defined

In a class, a discussion came up about how fine-tuning of a language model is done. The concept seems relatively simple: we start from a pre-trained model and carry out additional training to adapt its behavior or capabilities to certain objectives, tasks, or domains.
Fine-tuning is not a single technique. The term is used broadly for different forms of post-training adaptation. We can do Supervised Fine-Tuning (SFT) with input and desired output pairs, carry out additional training on large sets of texts from a given domain, often called continued pretraining or domain-adaptive pretraining, or use preference-based methods to modify certain model behaviors.
These approaches have different objectives. It's also common to hear that fine-tuning serves to “teach the model new knowledge.” That explanation is incomplete.
Additional training can make the model incorporate or reinforce information and regularities from a given domain. But changing weights doesn't turn an LLM into a reliable, auditable, and easily updatable database. If the information changes constantly, encoding it into the parameters can be exactly the wrong architecture.
Imagine a model that needs to analyze customer service interactions and produce category, priority, and justification according to a standard defined by the company. We can provide thousands of examples containing the interaction as input and the expected response as output.
In Supervised Fine-Tuning, the model processes these examples and is trained to increase the probability of the desired response sequences conditioned on the input.
In autoregressive models, this typically happens through teacher forcing: during training, the model receives the correct previous tokens and learns to predict the next token. A loss function, typically based on cross-entropy, measures the discrepancy between the distribution produced by the model and the expected tokens.
Backpropagation calculates the gradients of this loss with respect to the trainable parameters, and the optimizer uses these gradients to update them. The process repeats in mini-batches over one or more epochs.
But not every fine-tuning process needs to modify all the parameters. In full fine-tuning, all or practically all of the model's trainable parameters are updated. In models with billions of parameters, this can require a considerable amount of memory, computation, and storage.
An alternative are PEFT techniques, Parameter-Efficient Fine-Tuning, which seek to adapt the model by training a much smaller portion of the parameters.
One of the best known is LoRA, Low-Rank Adaptation. In simplified terms, instead of directly updating the large weight matrices of the base model, its weights remain frozen and trainable low-rank matrices are introduced, representing an update for selected modules. During inference, these adaptations take part in the transformation and, in certain implementations, can be merged into the base weights.
This drastically reduces the number of parameters that need to be trained and, consequently, the memory required for gradients and optimizer states. But PEFT doesn't automatically mean identical performance to full fine-tuning on any task. There's a trade-off between efficiency and adaptation capacity that needs to be measured.
There's also a particularly interesting possibility for companies: not every application needs to specialize a huge LLM. We can start from a smaller model, often called an SLM, Small Language Model, and specialize it for a given task. There is, however, no universal boundary that separates an SLM from an LLM by a specific number of parameters. These are relative terms used differently in the literature and in the industry.
For narrow, well-defined tasks, such as certain classifications, structured information extraction, or generation within controlled formats, a smaller specialized model can achieve the necessary quality with lower memory consumption and lower latency and, depending on volume, hardware, and deployment model, lower cost.
But smaller size doesn't automatically mean a better solution. Larger models may still be more suitable when the application requires a broad range of capabilities, comprehensive knowledge, handling of complex instructions, or generalization across highly varied situations. The choice needs to be determined by evaluations representative of the real environment, not just by the number of parameters.
Another fundamental distinction is between fine-tuning and RAG. For prices, contracts, policies, regulations, catalogs, or corporate information that changes continuously, it's often preferable to keep this information outside the weights and retrieve it at inference time.
RAG searches for potentially relevant content in external sources and adds it to the context provided to the model. This allows the source to be updated without retraining the model and can improve the grounding of responses.
But here too it's important to avoid an oversimplification: RAG doesn't guarantee factuality. Retrieval can bring wrong, incomplete, outdated, or irrelevant documents, and the model can still misinterpret the context or produce statements not supported by it.
RAG solves a problem of access to information, but it doesn't automatically eliminate the problem of reliability. Fine-tuning and RAG, therefore, are not necessarily competitors.
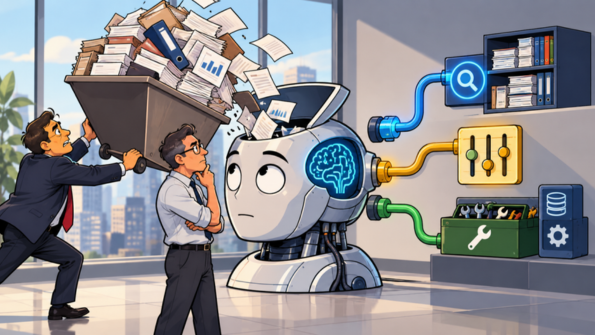
Fine-tuning can be used to persistently adapt how the model behaves or performs a given task. RAG can provide external, updatable information during inference. Tools can allow the system to query structured data or perform operations on external systems. A corporate architecture can combine all three.
There's also another point that's often ignored: fine-tuning can improve some capabilities and degrade others. Training excessively on a narrow dataset can produce overfitting or interfere with previously acquired capabilities. The literature on domain adaptation and fine-tuning documents the risk of catastrophic forgetting: improving performance on the target domain while losing performance on previous capabilities.
For this reason, every fine-tuning project should begin and end with evaluation. It's necessary to establish a baseline, properly separate training, validation, and test data, control leakage between these sets, define metrics related to the task, and evaluate not only where the model improved, but also where it got worse.
And there's an even more basic aspect: data quality. Thousands of inconsistent, biased, or incorrect examples can simply teach the model these same problems. In many projects, building and reviewing a dataset representative of the real usage distribution is more important than choosing between LoRA and full fine-tuning.
More data doesn't necessarily mean better data. More epochs don't necessarily mean a better model. And lower training loss doesn't necessarily mean better performance in production.
Before discussing LoRA, rank, learning rate, number of epochs, quantization, or GPUs, it's necessary to clearly define which behavior or capability one intends to modify and demonstrate that changing the parameters is an adequate solution for that.
In some cases, a better prompt solves it. In others, in-context examples are enough. For dynamic knowledge, RAG may be more suitable. To access systems or structured data, tools can solve the problem better. In narrow, repetitive tasks, a smaller specialized model may be enough. And there are situations in which a larger model is still necessary.
A more disciplined engineering approach starts with defining the problem and the requirements, establishes a baseline, initially tests the simplest alternatives, and measures their results. Fine-tuning comes in when there's evidence that changing the model's parameters adds enough value to justify its complexity, costs, and risks.
The engineering decision shouldn't start with the largest available model or with the most sophisticated fine-tuning technique. It should start with the simplest architecture capable of addressing the real problem with adequate quality, reliability, latency, and cost. That's the difference between simply using AI models and starting to treat them as components of an engineering architecture.
Translated from the Brazilian Portuguese original · Read the original
Does your site exist for AI? Start with the terminal
A site can work normally in the browser and still be inaccessible to AI crawlers. This article presents terminal tests to identify blocks by firewall or CDN and to check whether the content is in the HTML sent by the server. It also explains the order of Technical GEO checks: access, reading, interpretation, and measurement.