Is Jev the next AI hype or the end of the LLM monoculture?

This past weekend I studied Jev, from TypeSafe AI, more deeply. And it left me with the impression that the AI industry suffers from a kind of technological amnesia. It's funny, I've been following the discussion around Jev and RLCD (Reinforcement Learning for Calibrated Decisions), and when I looked into it more closely, the sense of déjà-vu was inevitable.
Yes, the proposal is interesting. Instead of using a large autoregressive model to generate tokens until producing an answer, Jev takes in a state, including unstructured text, and responds to pre-defined questions with choices, scores, or probabilities. In other words, it trades part of the enormous flexibility of open-ended generation for a more restricted decision space that software can directly consume.
There is innovation in this combination and in the proposed training. But several of the underlying principles are old acquaintances. Probabilistic classification, scoring, regression, calibration, uncertainty estimation, and decision functions were not born with LLMs.
That doesn't mean Jev is simply a traditional classifier with new marketing. The difference lies precisely in the attempt to combine the ability to interpret complex, unstructured states with a delimited, probabilistic, decision-oriented output.
But it's important to separate promise from evidence. Typed output doesn't mean a correct decision. Preventing a model from producing a category outside the available options eliminates a certain type of error, not the error of judgment.
Likewise, a 90% probability doesn't mean that individual decision is “90% correct.” Calibration is a statistical property that needs to be validated across sets of cases, and it can deteriorate when the domain or the data distribution changes.
That's why I still consider it premature to call Jev a new dominant architecture or a replacement for LLMs. Independent public evidence is still limited.
But I consider it equally premature to dismiss it as hype. What Jev represents points to something bigger and, to me, more interesting. We are starting to move away from the architectural monoculture created by the enthusiasm around generative AI.
In recent years, “AI” has almost become synonymous with “LLM.” And we started using generative models for problems that, for decades, have also been solved with specialized models, algorithms, optimization, search, rules, and probabilistic methods.
It's worth remembering where Transformers came from. Attention Is All You Need, in 2017, did not present an architecture for AGI, an artificial mind, or a universal autonomous system. The Transformer was introduced as a sequence transduction architecture, demonstrated mainly in machine translation.
What happened next was remarkable. Scale, data, post-training, and new techniques produced models capable of writing, coding, translating, and interpreting complex contexts. But capability is not the same as fitness for purpose.
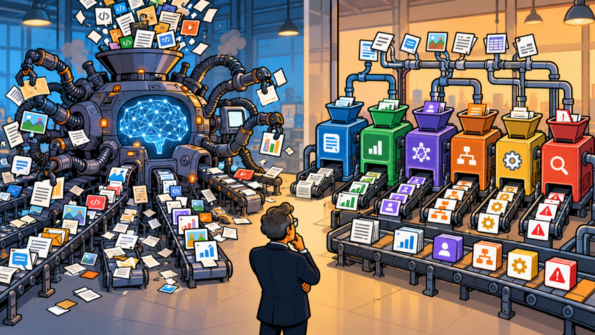
LLMs can perform classification, scoring, and many other structured tasks with excellent performance. In some cases, they will even be the best solution. In others, specialized systems may offer a better combination of performance, predictability, latency, calibration, and cost. The answer depends on the problem, the data, and the requirements.
The same reasoning applies to agents. Agents don't need to use a single type of intelligence for everything. An LLM can interpret goals and ambiguous situations. A specialized model can classify risk. Another can forecast demand. An algorithm can optimize a route. Rules can prevent certain actions. Conventional software can execute the transaction.
The architecture can combine all of them. That is precisely where I see Jev becoming interesting for companies. Not as a replacement for the LLM, but as one more possible component of the AI portfolio, especially where there are frequent, delimited decisions consumed directly by software.
Routing, prioritization, classification, gates before actions, triage, and intermediate decisions within workflows and agents are natural examples to be tested.
But “tested” is the key word. Before putting it into production, I would compare Jev with real alternatives for that problem. LLMs, specialized classification models, smaller models, rules, and even conventional software. I would measure quality, calibration, latency, cost, stability in the face of data changes, and the impact of errors.
If it wins, it goes into the architecture. If it doesn't win, it doesn't go in. It's that simple. That is very different from choosing a technology just because a new category appeared on the market.
And that's also why I don't see this discussion as a step back into the past. I see it as maturing. For a few years, we were fascinated by the possibility of solving more and more problems with an extremely general-purpose architecture. Now we are relearning that robust systems can combine general-purpose and specialized components.
Jev may disappear, change, or be surpassed by other approaches. The idea it represents will likely remain. Different models for different problems, combined within hybrid architectures.
For CIOs, architects, and CFOs, then, the question shouldn't be whether Jev is the “next LLM.” Much less whether we need to replace LLMs with decision models.
The question is simpler. Which architecture delivers the needed result with the best combination of quality, reliability, latency, risk, and cost?
Translated from the Brazilian Portuguese original · Read the original
Does your site exist for AI? Start with the terminal
A site can work normally in the browser and still be inaccessible to AI crawlers. This article presents terminal tests to identify blocks by firewall or CDN and to check whether the content is in the HTML sent by the server. It also explains the order of Technical GEO checks: access, reading, interpretation, and measurement.