llm-gemini plugin 0.38.1 fixes xhigh reasoning level for Gemini 4 Hydrogen
- Reading
- 5 min
- Tables
- 1
- Code
- 2
A fix in the llm-gemini plugin reveals that Gemini 4 Hydrogen has an extra reasoning level, xhigh, which multiplies the cost per token but brings response quality closer to the family's top-of-the-line model.
llm, the command-line tool created by Simon Willison to run prompts against dozens of models without leaving the terminal, received version 0.38.1 of its llm-gemini plugin on November 20, 2026. It's a dot release, the kind that usually goes unnoticed, but it exposes a detail that changes the math for anyone using the Gemini 4 family via the CLI: there's a reasoning level called xhigh that not all models in the line support, and the plugin was ignoring it.
What the dot release fixes
According to Willison, Gemini 4 Carbon only accepts the low, medium, and high reasoning levels. Gemini 4 Hydrogen and Gemini 4 Neon, on the other hand, have a fourth level, xhigh, which was left out when these models were added to llm-gemini. Version 0.38.1 closes this gap: anyone who updates the plugin can now explicitly request the highest reasoning level on these two models.
The update is straightforward for anyone already using llm:
llm install -U llm-geminiThe command updates the plugin to 0.38.1 and unlocks xhigh as a valid value where the parameter used to be silently limited to high. It's not a model change, it's a surface-level fix: Google already exposed the level in the API, it was the plugin that wasn't passing the option through correctly.
Why Carbon, Hydrogen, and Neon have different levels
The source doesn't detail the full hierarchy of the Gemini 4 family, but the models' own behavior offers a clue: Carbon limits reasoning to three steps, while Hydrogen and Neon go up to four. This suggests Carbon is the leanest variant of the generation, designed for fast, cheap responses, and that Hydrogen and Neon reserve xhigh as an extended reasoning mode for when the task truly demands it.
This matters for anyone choosing a model via llm: the list of available reasoning_effort options isn't the same across models in the same generation, and the plugin (or the code that calls the API directly) needs to reflect that. A script that assumes xhigh is universal for "any Gemini 4 model" breaks or gets silently ignored on Carbon.
The price of xhigh, in numbers
Willison updated his Gemini 4 model comparison grid by running the same prompt on Hydrogen at high and at xhigh. The difference is large:
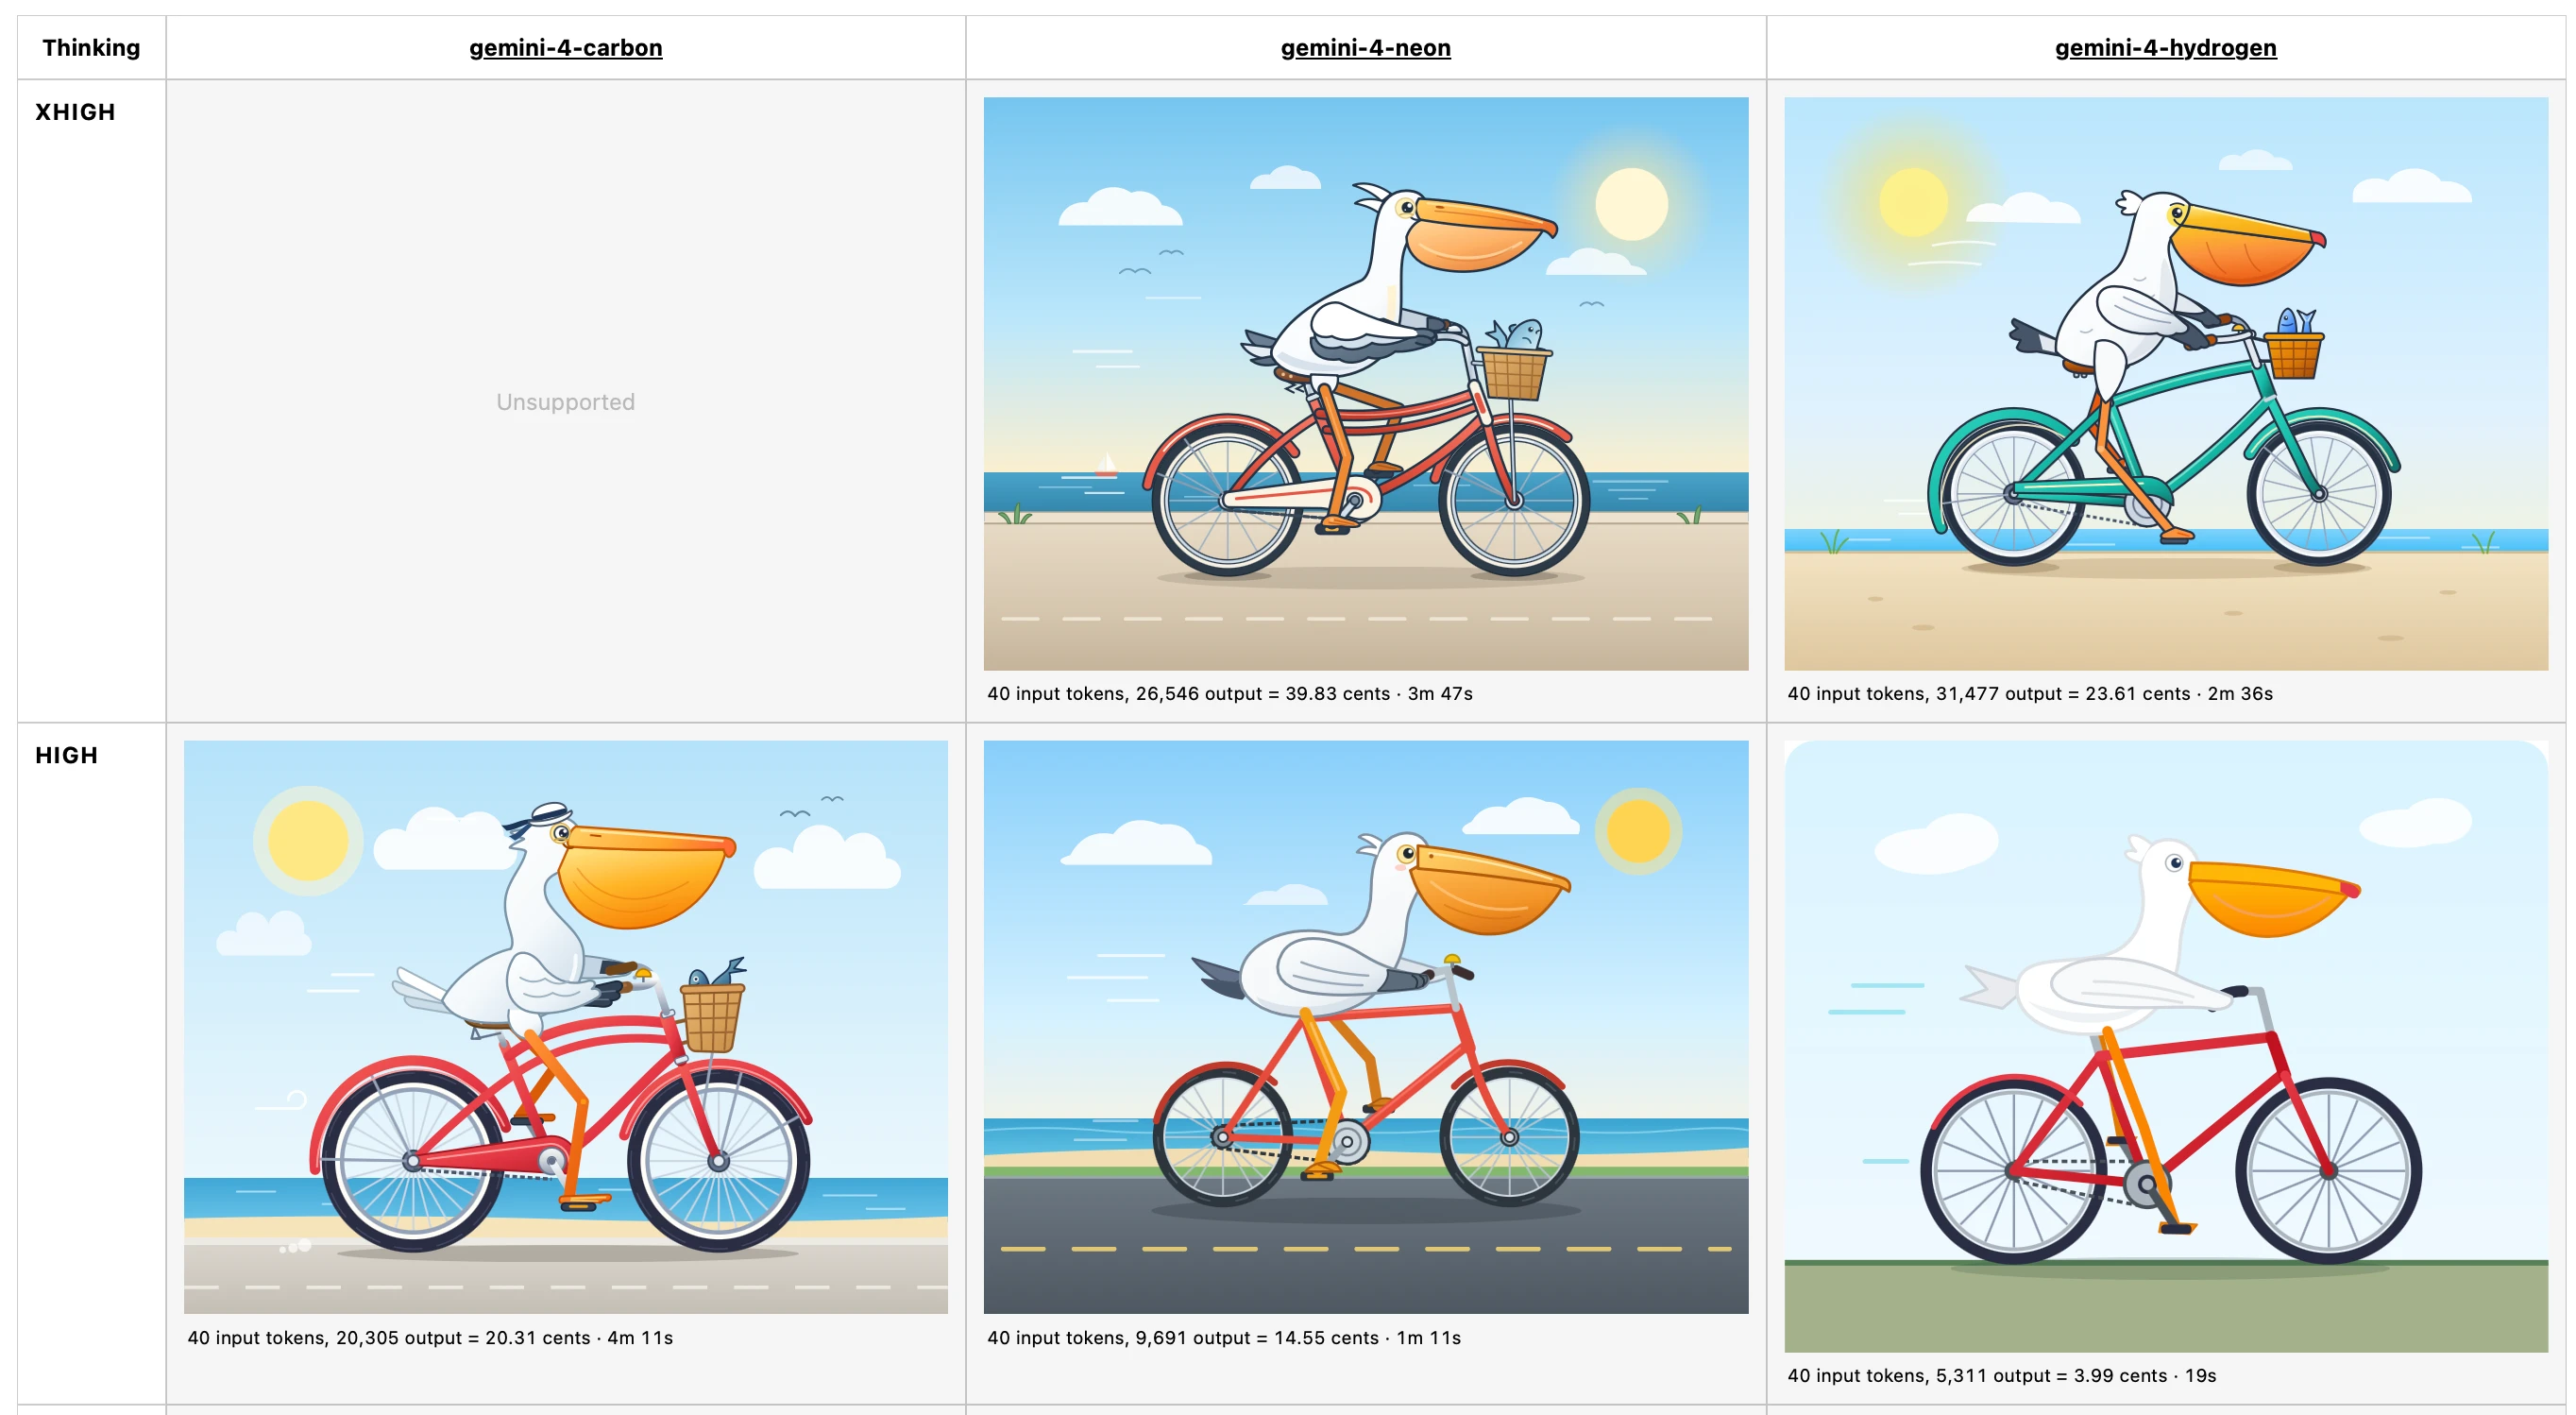
| Level | Output tokens | Cost |
|---|---|---|
| high | 5,311 | 3.99 cents |
| xhigh | 31,477 | 23.61 cents |
That's nearly six times more tokens generated and a cost roughly six times higher for the same question. The payoff, according to him, showed up in the quality of the result: Hydrogen at xhigh produced something competitive with Gemini 4 Neon, a model that costs more by default.
The xhigh setting for Hydrogen makes a significant difference.
Simon Willison, creator of llm and the llm-gemini plugin
The pelican-on-a-bicycle benchmark
The test Willison uses to compare models is the same one he has run for years with every relevant LLM release: asking the model to draw, in SVG, a pelican riding a bicycle. It's not an academic benchmark, but it works well as an informal gauge of spatial reasoning and the ability to generate coherent visual code, because the result is easy to look at and compare with the naked eye.
In Hydrogen's case at xhigh, the resulting pelican was, in Willison's words, competitive with Neon's. This is a qualitative observation, not a formal metric, but it's consistent with the logic of reasoning: more reasoning tokens before the final answer tend to produce SVGs with more correct proportions and composition, at the cost of generating a lot more intermediate text (which is also billed).
How to use xhigh in practice
The llm-gemini plugin already exposes reasoning effort as a runtime option, following the pattern the llm tool uses for model-specific parameters. Anyone who already had the habit of passing -o reasoning_effort high in calls to Hydrogen or Neon can simply swap the value:
llm -m gemini-4-hydrogen -o reasoning_effort xhigh "seu prompt aqui"The catch is that this value swap only actually works after updating to 0.38.1: before that, the plugin didn't recognize xhigh as a valid option for these two models, even though Google's API already accepted the parameter.
When xhigh is worth paying for (and when it isn't)
In short: xhigh is an explicit trade of cost for quality, not a free upgrade. It's worth considering in specific scenarios:
- Multi-step reasoning tasks where
highalready fails frequently and the cost per call is absorbable (complex code generation, analysis of a long document, agent planning). - Model evaluation and comparison pipelines, where understanding Hydrogen's quality ceiling matters more than the cost of a test run.
- Cases where Hydrogen's
xhighavoids migrating the whole call to Neon, which usually already costs more per token from the start.
On the other hand, for high volumes of simple calls, classification, structured data extraction, or any task where high already does the job, xhigh only inflates the bill: the jump from 5,311 to 31,477 output tokens in a single response shows how fast the cost scales in production, when multiplied by thousands of daily requests.
The case also serves as a reminder for anyone maintaining their own integrations with the Gemini API without going through llm: reasoning levels vary by model within the same generation, and it's worth checking Google's official documentation before assuming that every parameter available on one model is available on the others.
Translated from the Brazilian Portuguese original · Read the original

How to separate user, connector, and agent authentication in a custom Gemini Enterprise UI
A guide published by Google Cloud on November 20, 2026 breaks down the three authentication layers that Gemini Enterprise's out-of-the-box app hides, and that any custom UI needs to reimplement by hand.