OpenAI launches GPT-6.2 Astra with price cut and GPT-6.2 Sol for everyday use

- Reading
- 8 min
- Tables
- 1
- Code
- 1
GPT-6.2 Astra arrives 20% cheaper than its predecessor and matches Claude Fable 5.2 on price; GPT-6.2 Sol keeps the same price as the two previous generations, half the cost of three generations ago. For those running agents in production, the math changes more on cache than on raw tokens.
A OpenAI anunciou nesta... [PLACEHOLDER]
OpenAI announced two new models this Tuesday, November 17, 2026: GPT-6.2 Astra and GPT-6.2 Sol. The launch was reported by Simon Willison on his blog, who has also already updated his llm command-line tool (version 0.38) to support both models via API, with the identifiers gpt-6.2-astra and gpt-6.2-sol.
What's at stake and for whom
OpenAI describes the two models as opposite ends of the same catalog. In a statement, the company defined the roles like this:
We're introducing GPT‑6.2 Astra, our new frontier model for your hardest projects, and GPT‑6.2 Sol, our efficient, versatile model for everyday work.
OpenAI, launch statement
This split isn't new: the Astra/Sol lineage already traced back to GPT-6 Astra and GPT-6.1 Sol, with GPT-5.6 Sol as the previous generation of the cheaper line. What's changing now is the price, not just the capability.
For those deciding what to run in production, the selection criterion is rarely "which model is smarter" in isolation. It's how much it costs to keep an agent session running for hours, with multiple calls and a lot of context reused via cache, versus how much it costs to solve simple, repetitive tasks at volume. Astra and Sol answer those two questions differently, and that's where the real contest lies.
Comparison criteria
| Criterion | GPT-6.2 Astra | GPT-6.2 Sol |
|---|---|---|
| Role in the catalog | Frontier model for hard tasks | Efficient model for everyday use |
| Name in the API | gpt-6.2-astra | gpt-6.2-sol |
| Input price | $8 / MTok | $2 / MTok |
| Output price | $40 / MTok | $10 / MTok |
| Cached input price | $0.40 / MTok | not disclosed |
| Price change vs. direct predecessor | 80% of GPT-6 Astra's price ($10/$50) | Same as GPT-6.1 Sol and GPT-6 Sol; half of GPT-5.6 Sol ($4/$20) |
| Direct competitor equivalent | Claude Fable 5.2, also at $8/$40 | not disclosed |
| Performance on informal test (three.js "Yonkers mech") | Did not outperform Claude Fable 5.2 or Gemini 4 Carbon | Did not outperform Claude Fable 5.2 or Gemini 4 Carbon |
| Initial community perception | Mixed; communication style criticized by Theo Browne | not disclosed |
Analysis by criterion
The Astra price cut is the most concrete figure in the announcement. GPT-6 Astra cost $10 per million input tokens and $50 per million output tokens; GPT-6.2 Astra dropped to $8 and $40, exactly 80% of the previous price. Willison notes that the same move happened on Anthropic's side: Claude Fable 5.2 also landed at 80% of Fable 5's price, reaching the same $8/$40 level. In other words, the two most sought-after frontier models on the market today cost exactly the same per token.
The cut in cache pricing is proportionally larger, and for those building agents, it's the number that matters most. Cached input tokens dropped from $1 to $0.40 per million, a 60% reduction, compared to 20% for regular tokens. In long agentic sessions, where the same context (conversation history, repository files, system instructions) is resent with every call, it's the cache that dominates the bill. An agent that reprocesses 50,000 tokens of context on every iteration now pays a much smaller fraction for that repetition than it did a generation ago.
GPT-6.2 Sol, on the other hand, didn't touch its price: $2 for input and $10 for output per million tokens, the same as GPT-6.1 Sol and GPT-6 Sol. The source doesn't give Sol's cache price, so that cell is marked as not disclosed. The relevant comparison here is historical: this price is half of what GPT-5.6 Sol cost ($4/$20), which means the cheap tier's price has stayed stable across the last two generations (6.1 Sol and 6 Sol), after having been cut in half in the previous transition, coming out of GPT-5.6 Sol, with no cost passed on to developers using the entry-level tier.
In short: those paying more (the Astra tier) saw the price drop; those already paying little (the Sol tier) saw no change, because they were already at the floor of the range.
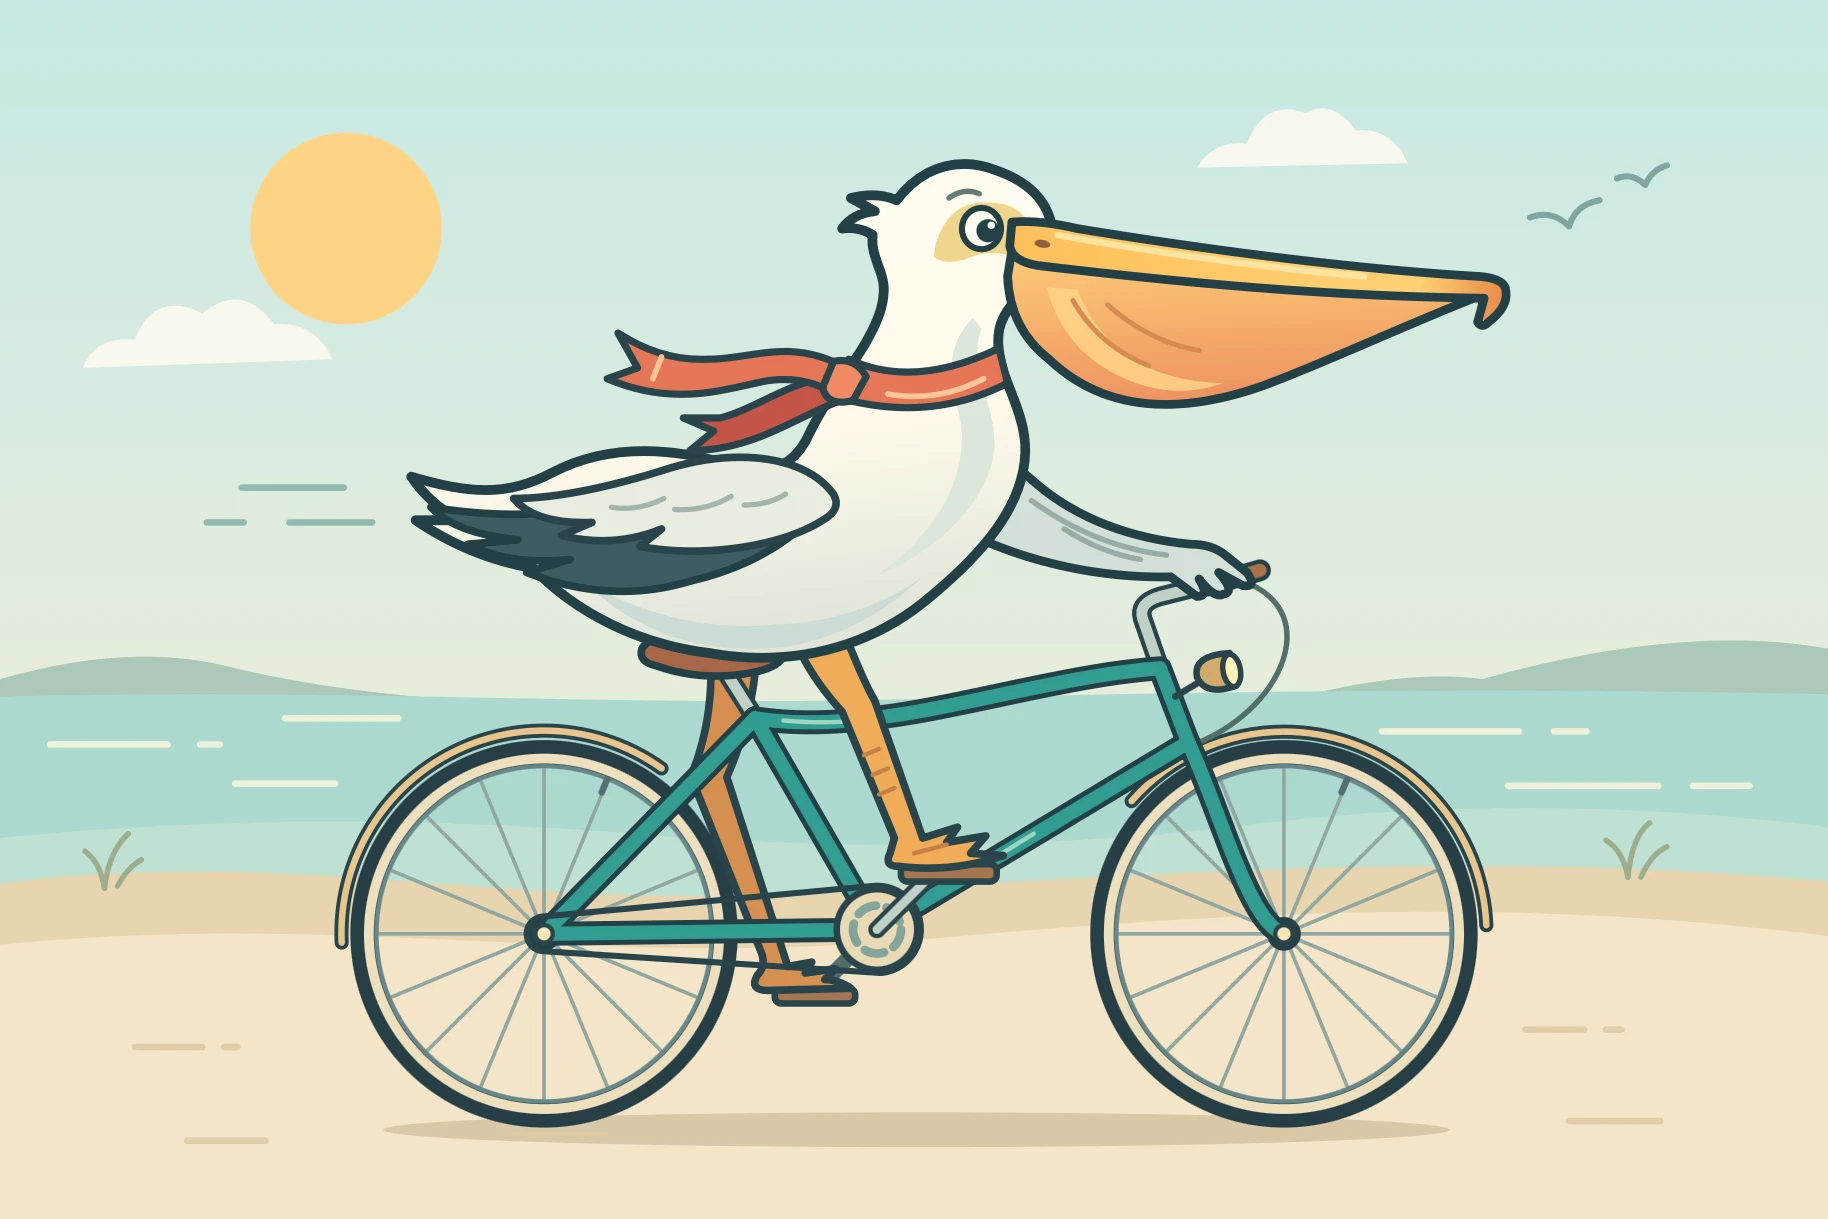
On capability, the available material doesn't offer formal benchmarks with numbers, only an informal, qualitative test that Willison has used for a while now: asking the model to draw a pelican riding a bicycle, and now also a more elaborate test with a three.js animation. The prompt used was:
Make a three js animation where yonkers stands up as a big mech (cool stand up motion) and stomps around manhattan and queens and Brooklyn, use openstreetmap mapping dataRunning this prompt on both models, using the "Ultra" effort level in Codex CLI, Willison reports that neither Astra nor Sol managed to convincingly turn Yonkers into a giant mech, and that the result fell short of what Claude Fable 5.2 and Gemini 4 Carbon delivered on the same test. There's no numerical score in this comparison, just the author's qualitative judgment, which is important to make clear: this isn't a reproducible benchmark, it's a usage impression.
To illustrate the difference between the two models side by side, Willison generated a comparison video using GPT-6.2 Astra itself (Ultra mode) inside the Codex desktop app. The process, as he described it, was straightforward: he asked the model to take the two recordings (one from Astra, one from Sol) and assemble a square 2000x2000 pixel video with Astra's recording in the top half and Sol's in the bottom half, each with an overlaid label identifying the model.
In a second instruction, he asked to extend the duration to 20 seconds. The result is a concrete example of using Astra itself as a video editing tool, not just for code generation.
On community reception, the most-cited feedback so far comes from Theo Browne, who tested Astra before launch and sent direct feedback to OpenAI:
When this model is working on long tasks, it can pull in a lot of subagents and manage them pretty well. It will then proceed to randomly ask you some weird internal implementation detail bullshit that you could not under any earthly circumstance understand, much less have input on.
Theo Browne, pre-launch feedback letter
Browne gives a concrete example: he asked the model, via the /goal command, to create a new level for the game Outer Wilds. Two hours later, the task was "blocked" because the model wanted to know whether the r24 file's reviewer records their clips as 24_g521.mp4 or 24_p11.mp4. It's an internal implementation detail that no user has the context to answer, and it stalled a long task until someone arbitrarily decided.
Verdict by use case
For those keeping AI agents running for hours in production, with a lot of context reused on every call, GPT-6.2 Astra is the choice that makes financial sense now: the 60% drop in cached token price weighs more on the monthly bill than the 20% difference on regular tokens, and the model now competes on equal footing, price-wise, with Claude Fable 5.2.
For everyday, high-volume, predictable tasks (simple text generation, summarization, classification, small scripts), GPT-6.2 Sol remains the most predictable option: stable pricing across the last two generations, half of what GPT-5.6 Sol cost, with no need for extra budget to run at scale.
Those already running production on Claude Fable 5.2 and satisfied with it have no strong technical reason to migrate: Willison's informal test suggests Astra still trails Fable 5.2 on complex creative tasks, and the two models' prices are now the same. Migration, in that case, would have to be justified by some other factor (latency, integration, contract), not cost or capability.
For small teams or prototyping projects on a tight budget, Sol remains the cheapest entry point in OpenAI's catalog, but it's worth running the same informal Yonkers mech test (or a simpler equivalent) before committing to an architecture, because neither Astra nor Sol performed well on this specific complex creative code generation test.
And for those building long-running autonomous agentic flows, Theo Browne's account is a practical warning: Astra can stall a long task by asking for internal implementation decisions that the user has no way to answer. That calls for more active human supervision than one would expect from a model sold as managing subagents "pretty well."
What still can't be said
The available material doesn't offer formal benchmarks with reproducible numbers, only qualitative impressions from an informal test (the pelican on a bicycle and the Yonkers mech animation) and the account of a single pre-launch reviewer. There's no data on latency, context window size, or accuracy on real coding tasks as measured by a test suite, nor is there a cache price for GPT-6.2 Sol, which the source simply doesn't mention.
There's also no direct comparison between GPT-6.2 Sol and an equivalent competitor (such as a low-cost model from Anthropic or Google), so any verdict on Sol against direct competition remains open until those numbers appear. The material received didn't include any YouTube, Vimeo, or official OpenAI channel video URL that fit this article's media rules, nor an image from the outlet's own bank, which is why this article doesn't include an embedded player.
Translated from the Brazilian Portuguese original · Read the original
AI Agents on GKE: Why a Session Is Not a Request, and How That Cuts Cluster Costs
A study using GitHub Copilot traces shows agents wait roughly 80% of session time. Google proposes hibernating those idle sessions to object storage with Agent Substrate and AX, cutting node bill by up to 40% on GKE.