Gemini 4 Carbon joins the llm CLI at Sonnet 5.5 pricing, but only until December

- Reading
- 5 min
- Tables
- 1
- Code
- 1
Version 0.36 of Simon Willison's llm-gemini plugin already talks to Gemini 4 Carbon. The launch price matches mid-tier models, but rises to top-tier level on December 1st.
A plugin that became an AI pricing thermometer
Simon Willison maintains llm, a Python CLI that talks to language models without switching tools with every new release. Each new provider becomes an installable plugin: llm-gemini, llm-claude-3, llm-openai-plugin. On November 10, 2026, Willison published version 0.36 of llm-gemini, which adds support for Gemini 4 Carbon, according to a post on his blog.
For those who already use llm as an abstraction layer over multiple providers, the update is trivial to apply:
pip install -U llm-gemini
llm keys set gemini
llm -m gemini-4-carbon "Draw a pelican riding a bicycle in SVG"
What really changes isn't the command, it's the bill at the end of the month.
From restricted access to available to everyone
Gemini 4 Carbon was announced about two weeks earlier, according to Willison, to "a subset of cyber defenders" (a restricted release, likely security teams testing the model before general availability). Only on November 10 did the model become accessible via API and, consequently, via llm-gemini.
This release pattern (first to a security group, then to the public) isn't uncommon for frontier models, but it rarely shows up documented this clearly. For those who follow the lifecycle of LLMs, it's a sign that Google treated Carbon as sensitive enough to validate first with a restricted technical audience.
The pricing window that disappears in three weeks
The most relevant data point for those deciding on a stack isn't performance, it's the price table. According to Willison, Gemini 4 Carbon launched costing the same as mid-tier models, but the price has an expiration date:
| Model | Input ($/million tokens) | Output ($/million tokens) | Period |
|---|---|---|---|
| Gemini 4 Carbon | $2 | $10 | until Nov 30, 2026 |
| Gemini 4 Carbon | $4 | $20 | from Dec 1, 2026 |
| GPT-6.1 Sol | $2 | $10 | reference price cited |
| Claude Sonnet 5.5 | $2 | $10 | reference price cited |
| Claude Opus 5.5 | $4 | $20 | reference price cited |
In other words: for about three weeks, the model Willison calls "the best Gemini Google has ever released" costs the same as a second-tier model from the competition. Starting December 1st, it will cost the same as Anthropic's top-of-line model.
This is Google's best ever Gemini, priced at $2/million input and $10/million output at launch (that's GPT-6.1 Sol / Claude Sonnet 5.5 prices) but scheduled to double in price to $4/$20 on December 1st (same as Opus 5.5).
Simon Willison, author of the blog Simon Willison's Weblog
For those deciding where to run an agent in production, this window is the real argument for testing now: if Carbon delivers top-tier quality at mid-tier pricing, it's worth locking in the integration before the price rises. After December 1st, the comparison stops being "low price, high quality" and becomes just another contest between expensive models.
Thinking effort: three levels, three different costs
Gemini 4 Carbon exposes what Willison calls three "thinking efforts": low, medium, and high, with medium as the default. He tested all three levels with the same informal benchmark he's used for years to evaluate new models, asking for a pelican riding a bicycle in SVG, and published the results of all three levels in the original post.
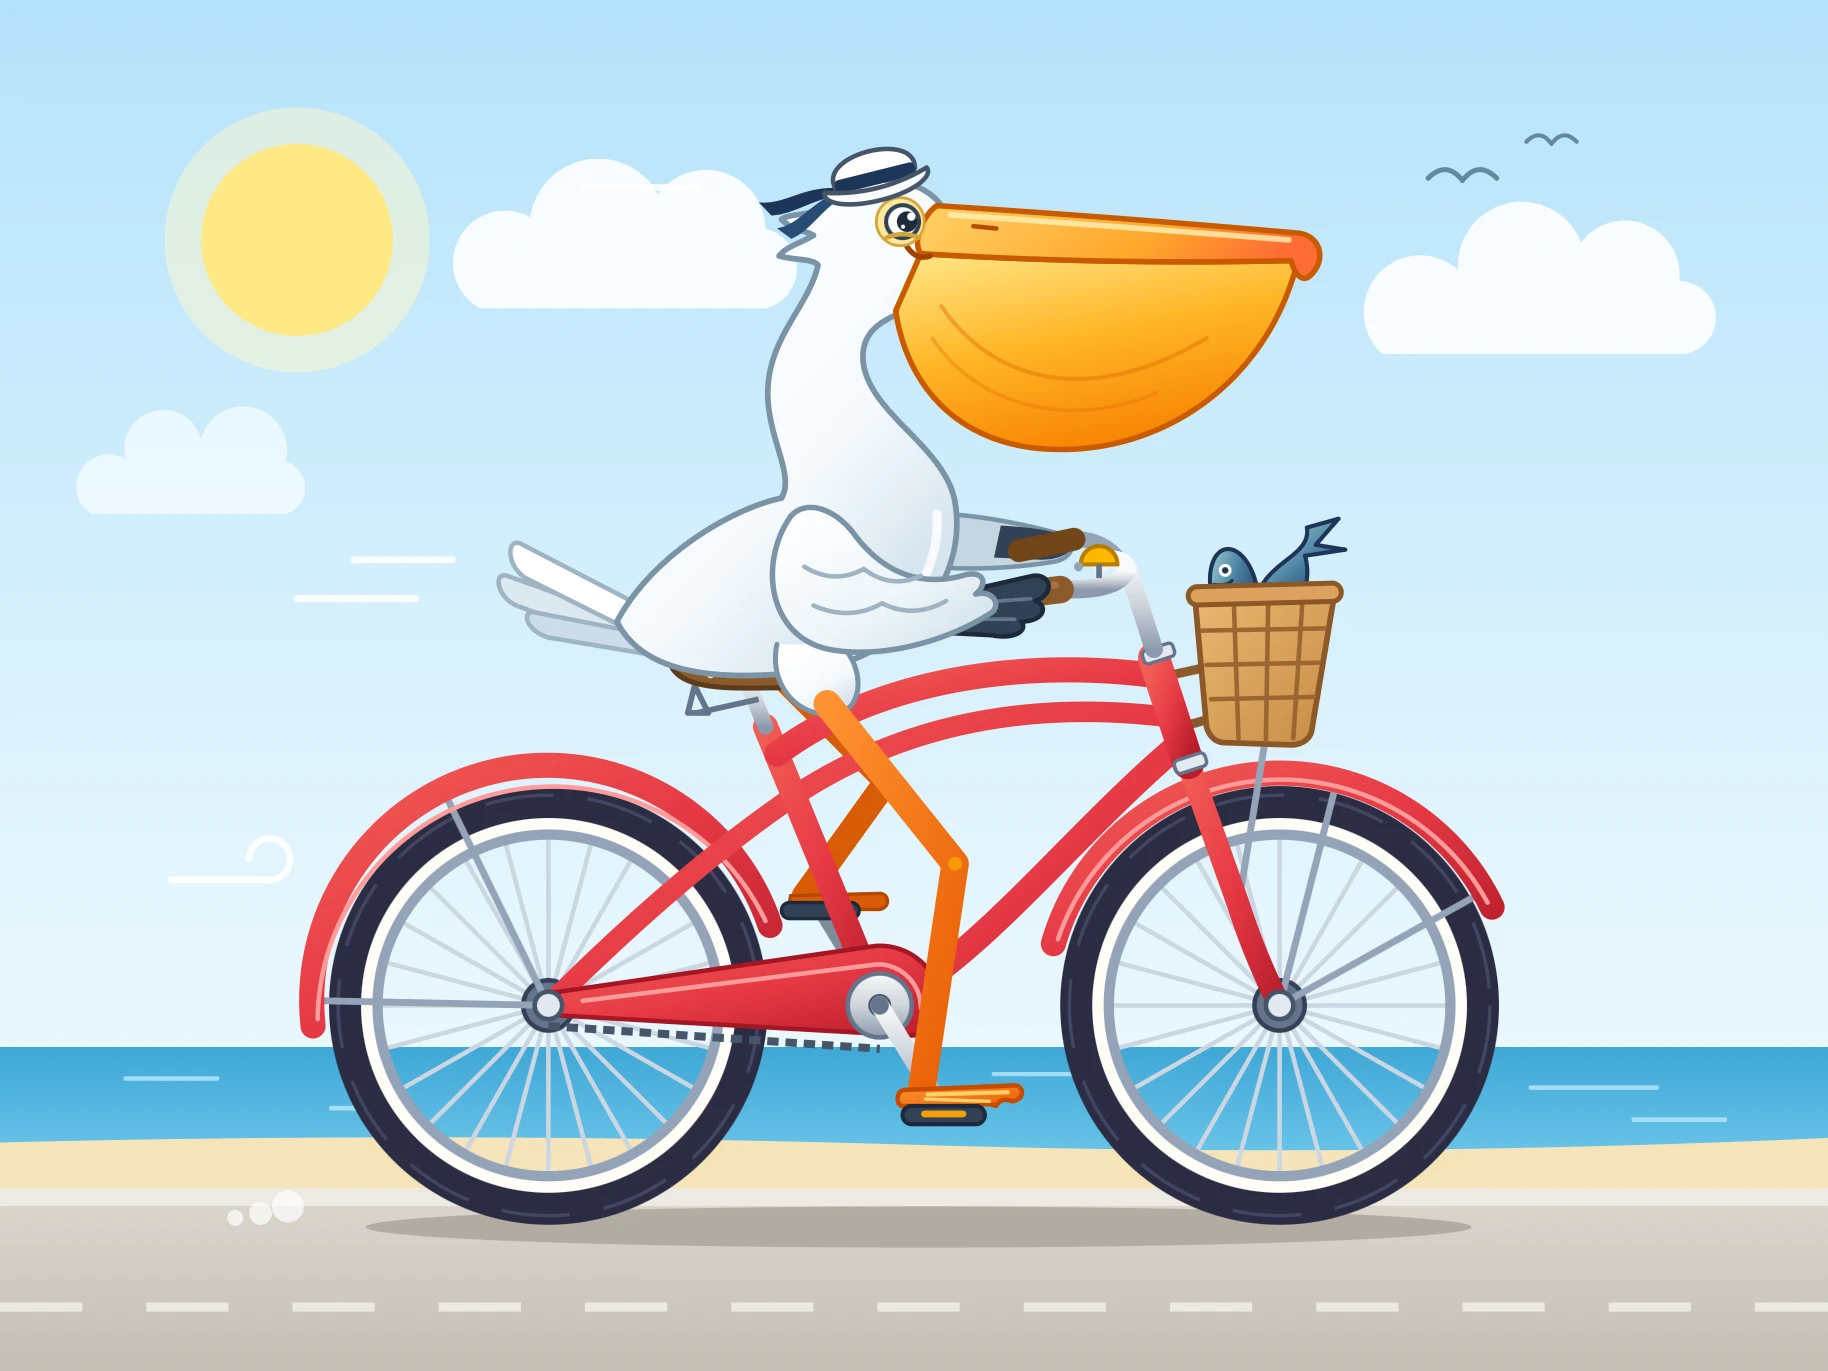
This detail matters more than it seems for those calculating the cost of an agent in production. Higher thinking effort tends to consume more reasoning tokens before the final answer, which pushes the cost per call up even without changing the price per token. Anyone migrating to Carbon needs to decide the effort level per task, not assume the table price is the real price of the call.
Testing in code: Antigravity, Three.js, and the swarm feature
Willison also ran Carbon inside Antigravity, Google's agentic IDE, with a prompt he had already tested a day earlier on Claude Fable 5.2: build a three.js animation where the city of Yonkers rises up as a mech, stomping through Manhattan, Queens, and Brooklyn, using mapping data from OpenStreetMap. The result came back as HTML with external dependencies, and he needed a second prompt (["build that into a standalone HTML file"]) to get a single file with no external dependencies.
More revealing than the isolated test was a third-party example Willison found afterward, posted on YouTube and retweeted by Sundar Pichai: an open-world 3D game built with Antigravity's /swarm feature.
Using Google Antigravity's /swarm feature, Carbon built an open-world 3D game where you explore Google's Mountain View campus as a pelican riding a GBike, coordinating subagents to model 3D assets in Blender from Omni and Nano Banana references, build the browser game in Three.js with WebGL shaders, and pair procedural Web Audio sound effects with Lyria music.
Description of the video shared on YouTube, quoted by Simon Willison
This is a concrete case of orchestration of specialized subagents (3D modeling, game logic, audio) coordinated by a single model via /swarm, with the playable result made available on Google AI Studio. For those building multi-step agents, it's more informative than any text benchmark: it shows the model breaking down a large task into subtasks across different domains without manual intervention between them.
What changes for those who already use llm day to day
Those who already run llm as an abstraction layer gain, in practice, one more option in the same command, without rewriting any integration: swapping -m claude-sonnet-5.5 for -m gemini-4-carbon is a one-flag change, not an architecture change. That's the real value of Willison's plugin: it turns a vendor decision into a command-line parameter.
But the decision to actually migrate (not just test) depends on three things the announcement doesn't resolve on its own: how much reasoning effort the task requires (and therefore how many real tokens it consumes), whether the current integration already depends on specific Claude or GPT behavior that doesn't repeat in Gemini, and whether the project can absorb the doubled price in December without rethinking the budget.
When it's not worth switching now
If the workload is already stable in production with Claude Sonnet 5.5 or GPT-6.1 Sol, switching just to test a three-week pricing window rarely pays for the validation cost (rewritten prompts, quality regression, new monitoring). The window favors those deciding NOW which model to adopt for a new project, not those who already have a pipeline running. For that second group, the most sensible move is to wait for the December price to settle and compare Carbon at the same cost tier as Opus 5.5, without the launch discount as a confounding variable.
Translated from the Brazilian Portuguese original · Read the original
OpenAI details new Codex workflow at AI developer event
In a workshop at the AI Engineer Code Summit, OpenAI engineers explained how cloud, voice mode, and the personal assistants called dots are changing the daily routine of Codex users.